Showing posts with label ADF. Show all posts

Saturday, August 28, 2021

How to Flatten JSON in Azure Data Factory?

When you work with ETL and the source file is JSON, many documents may get nested attributes in the JSON file. Your requirements will often dictate that you flatten those nested attributes. There are many ways you can flatten the JSON hierarchy, however; I am going to share my experiences with Azure Data Factory (ADF) to flatten JSON.

The ETL process involved taking a JSON source file, flattening it, and storing in an Azure SQL database. The attributes in the JSON files were nested, which required flattening them. The source JSON look like this:

{

"id": "01",

"name": "Tom Hanks",

"age": 20.0,

"email": "th@hollywood.com",

"Cars":

  {

  "make": "Bentley",

  "year": 1973.0,

  "color": "White"

  }

}

The above JSON document has a nested attribute, Cars. We would like to flatten these values that produce a final outcome look like below:

{

"id": "01",

"name": "Tom Hanks",

"age": 20.0,

"email": "th@hollywood.com",

"Cars_make":  "Bentley",

"Cars_year":  "1973.0",

"Cars_color":   "White"

}

How do we do it by using ADF?

Let's create a pipeline that includes the Copy activity, which has the capabilities to flatten the JSON attributes. Let's do that step by step.

First, create a new ADF Pipeline and add a copy activity.

Fig 1: Copy Activity in ADF


Next, we need datasets. You need to have both source and target datasets to move data from one place to another. In this case source is Azure Data Lake Storage (Gen 2). The target is Azure SQL database. The below figure shows the source dataset. We are using a JSON file in Azure Data Lake.

Fig 2: Source dataset

We will insert data into the target after flattening the JSON. the below figure shows the sink dataset, which is an Azure SQL Database.

Fig 3: Sink dataset

Please note that, you will need Linked services to create both the datasets, this article will not go into details about Linked Services, to know details you can look into the Microsoft document.


3. Flattening JSON

After you create source and target dataset, you need to click on mapping as shown below figure 4 and follow the steps:

Fig 4: Flattening JSON

a) At first import schemas
b) Make sure to choose value from Collection Reference
c) Toggle the Advanced Editor
d) Update the columns those you want to flatten

After you have done above, then save it and execute the pipeline. You will find flatten records are inserted to the database as shown in fig 5.


Fig 5: Saved data into the table after flattening


Be cautious

Make sure to choose "Collection Reference" as mentioned 3.b, if you forget to choose that then the mapping will look like below Fig 6:

Fig 6: Without putting collection reference


If you look at the mapping closely from the above figure 6, the nested item in the JSON from source side is: 'result'][0]['Cars']['make'] which means it will only take very first record from the JSON. If you execute the pipeline you will find only one record from JSON file is inserted to the database. So it's important to choose Collection Reference.

In summary, I found Copy Activity in Azure Data Factory make easier to flatten the JSON, you don't need to write any custom code which is super cool.


Sunday, June 6, 2021

Why Power query as a transformation activity in Azure Data factory and SSIS?

This blog post will describe how power Query activity in ADF and SSIS can be useful. As well as, I will share the differences of Power Query activity between SSIS and ADF.

Why Power Query and When to use it?

When data engineer works for transformation pipeline they get different activities like lookup, merge, data conversion etc. in their preferred ETL tool. ETL tools like Azure data factory (ADF) got Dataflow and Databricks to solve complex transformation. In addition, ADF introduced 'Power Query' (previous name data wrangling) as an activity. Please note that, Power query is still in preview for both Azure Data Factory (ADF) and SSIS. 


Fig 1: Power Query in ADF

Despite having many activities in Azure data factory why we need Power Query? Let's share my experience when Power Query have chosen as an activity in the pipeline.  The task was to get data from complex excel files with many calculation and more than 1000 columns which is used by business as an application. Yes! you got it right, it's an excel application, organization still uses excel as an application!!  A few transformed and calculated columns need to go to the modern data warehouse from the excel files. 

In this scenario, thought about what would be the best activity to choose from: DataFlow, Databricks or Power Query? well, I would say all of them may work but Power Query was the best choice.

Let me explain, why? Since the source file is excel and it's got  more than 1000 columns with many calculation inside, It's almost impossible for a Data Engineer to find out how to derive the expected outcome where no mapping or transformation logic is provided. By using Power Query visual transformation, business expert and I were able to work closely and produce the output in a very short period of time. 


Fig 2: Power Query transformation in ADF

 As a Data Engineer, when you work with dataflow or Databricks or any other transformation activity in ETL tool, you follow the documented mapping logic and build the pipeline. It means transformation rules and mappings are predefined. However, when transformation rules are yet to discover then best to start with Power Query. You can simply start with Power BI desktop to work together with business to produce the expected outcome. And when output is verified and accepted then then copy the M Query to ADF Power Query activity or SSIS Power Query source. In fact, now you have the transformation rules in the M Query so if you like to use other transformation activity like dataflow or Databricks you can use that too.


What works in SSIS but not in ADF?

Power Query activity is in Preview for both SSIS and ADF, however; if you choose ADF then you need to convert the source file from .excel to .csv since Power Query for ADF doesn't support .excel as source dataset.


Fig 3: Source dataset for Power Query

However, if you work with Power Query in SSIS then it support excel as source. On Contrary, in SSIS; when you are working with Power Query Source, it doesn't have user interface to make the transformation like ADF. The obvious reason is, you can use Power BI desktop to do the transformation and then copy the M query (Power Query generate M syntax which called M Query) from Power BI and paste it to Power Query Source in SSIS.

Fig 4: Power Query in SSIS


In summary, Power Query in both SSIS and ADF is useful Activity and new feature which still in preview, hence there might be many different scenarios where you want to use Power Query activity, however; this article is based on my experiences with Power Query activity in ADF and SSIS. It's also interesting to know that, The user interface you get under ADF Power Query is identical to Power BI, however, not all M query is supported by ADF Power Query yet.


Sunday, April 25, 2021

Handling SQL DB row-level errors in ADF (Azure data factory) Data Flows

If you are working with ADF (Azure data factory) data flows then you may have noticed there is a new feature released in Nov 2020 which is useful to capture any error while inserting/updating the records to the SQL database.

Fig 1: Error row handling at sink database

For error handling there are two options to choose from:

1) Stop on first error (default)

2) Continue on error


                                                    Fig 2: Error row handling options

By default, ADF pipeline will stop at the error. However, the main purpose of this feature to use option "Continue on error" to catch and log the error so that we can look at later and take action accordingly. 

Let's fill up the settings to catch errors rows, below figures show the settings and will also describe each setup (Please follow the numbering in the figure 3).

1) Error row handling: Since we wanted to catch the error so we have chosen "Continue of error" at Error row handling.

Fig 3: Settings Continue on error

2) Transaction Commit: Choose whether the data flow will be written in a single transaction or in batches, I have chosen single, it means whenever there is failure it will store the record on the other hand batch will store error records when full batch is completed.

3)Output rejected data: You need to make this check mark TRUE to store the error rows. The whole point of error row handling is you want to know the error records; if so, please tick check mark. Though you can avoid this, in that case pipeline will run but if there is any error you will not know which records causes the error.

4) Linked Service: Put the linked service and test the connection

5)Storage folder path: Storage path need to mention here, it's the path where you would like to store the error records in a file.

6)Report success on error: I don't put report on success checkbox to TRUE since I wanted to know if there is a failure.


After the settings, when you run the pipeline and if there is any error in the dataset, it will be stored in your storage folder as you have provided at point no 5 in the settings.


In general, when there is a failure at the time of inserting records to the database it takes sometime to find out the reason of failure. You may have to go through large chunk of dataset and look for miss match of data types or NULL value etc. to find out the root cause. Through this feature the error records will be captured and stored in the storage so you will be able to identify the reason for any error very quickly. And if you would like to ingest those error rows then you can fix those records and re-run the pipeline.

Tuesday, February 23, 2021

How to add local timestamp end of the files in ADF?

This article will describe how to add your local timestamp at the end of the each file in Azure Data Factory (ADF). In general, ADF gets a UTC timestamp, so we need to convert the timestamp from UTC to EST, since our local time zone is EST.

For example, if the input Source file name in SFTP is "_source_Customer.csv", then the expected outcome will be, "_source_Customer_2021-02-12T133751.csv". This means that the pipeline should add '_2021-02-12T133751' to the end of each file. This will work dynamically, which means that any file you pass from the source will have the timestamp added to it by using an ADF regular expression.

Let's set a simple pipeline and explain the scenario in a few steps. In this example, we receive files from an event based trigger and hold the file name in a parameter. The main part of this article is how to append the current date and time to the end of the file name we received. Please note that event based triggers will not be discussed here. If you like to know more about how to create trigger, please follow this link.

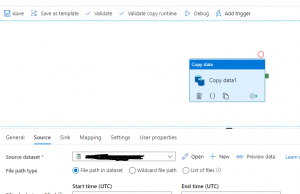
Step 1: Add Copy Activity

Create a simple pipeline with at least one Copy activity that connects a source and a sink, similar to what is shown in Fig 1.


                                          Fig 1: Pipeline with Copy Activity
 

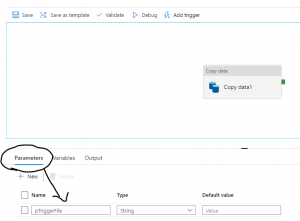
Step 2: Adding a parameter to receive the file name 

Before adding the expression, we need to have a parameter in the pipeline that will catch the filename from a trigger. For the time being assume that the trigger will give us the file name and the parameter is to hold the filename.
 
                                                 
                                                              Fig 2: Adding parameter

Step 3: Prepare the sink dataset

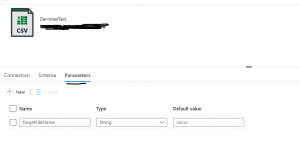
In the Copy data activity there is a Sink dataset that needs a parameter. Click on the Sink dataset and when it opens, you will find the view similar to Fig 3.

                                                                         
                                                                                Fig 3: Adding parameter to the dataset
 
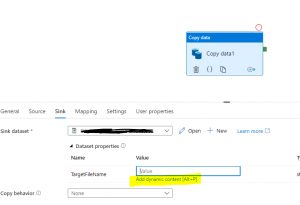
To add parameter to the dataset, click New and add the parameter name. Select the type, which should be a string. Now you you will see the sink dataset looks like Fig 4. The value edit box is where you need to add the dynamic content.
                                             
                                                  Fig 4: Dynamic content to add the timestamp


Step 4: Setting up a dynamic expression

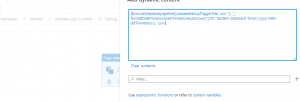
Now, let's create the dynamic expression. As soon you hit the 'Add dynamic content', shown in Figure 5, you will able to write the expression that will convert the UTC timestamp to EST and then pad end of the file.

                                         
                                                                  Fig 5: expression language
 
We apply a number of functions to the pTriggerFile parameter from Step 1. Let's have closer look at the expression:
@concat(replace(pipeline().parameters.pTriggerFile,'.csv',''), '_', 
formatDateTime(convertTimeZone(utcnow(),'UTC','Eastern Standard Time'),'yyyy-MM-ddTHHmmss'), '.csv')

Find out the explanation of the above expression.

  1. First we need to get the filename from the parameter, pTriggerFile. The value here will be: _source_Customer.csv
  2. Next we use REPLACE() to replace the .csv with empty string : replace(pipeline().parameters.pTriggerFile,'.csv',''). This case, we get:  _source_Customer
  3. We need to get the timestamp. To do that, we convert utcnow() to EST with this function: convertTimeZone(utcnow(),'UTC','Eastern Standard Time')
  4. We want to format the date, and use this: formatDateTime(convertTimeZone(utcnow(),'UTC','Eastern Standard Time'),'yyyy-MM-ddTHHmmss'), which will return a value like: 2021-02-12T133751
  5. We put this all together with @concat(Step1,'_', 'Step4','.csv'), which will return _source_Customer_2021-02-12T133751.csv

We learned how to add local timestamp end of any file, though in this case, the source file was a .csv. However, you can follow the same process for .txt file where you only need to change '.csv' to '.txt' in the expression.

Saturday, January 30, 2021

How to work with SQL Store procedure output parameters in Azure data factory

To facilitate native SQL code we have stored procedure support in Azure Data Factory (ADF). When we work with stored procedures, mostly we use input parameters, however, a stored procedure can also have output parameters. In this case, we need to deal with return values, similar to how a value is returned by a function. This article will describe how you can work with stored procedure output parameters in ADF.

ADF has the SQL Server Stored Procedure Activity, which is used for any stored procedure you have in a SQL Server database. ADF also has a Lookup activity in which you can use a stored procedure. The example will use the Lookup activity to execute a stored procedure in a database.

Let's start by creating a stored procedure (SP) with an output parameter:

CREATE PROCEDURE [ETL].[sp_testprocOutParm]
(
 @input  VARCHAR(10),@Iambit BIT OUTPUT)
AS
BEGIN
IF @input >= '1'
BEGIN
    SET @iambit = 1;
	RETURN;
	END
END;

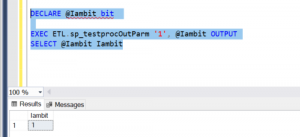
Let's see if the SP returns the expected value. Well, how do we execute the SP in SQL Server Management Studio (SSMS)? Please write below syntax to find the outcome.

DECLARE @Iambit bit 

EXEC ETL.sp_testprocOutParm '1', @Iambit OUTPUT
SELECT @Iambit Iambit

You should have outcome like below Fig 1.

Fig 1: Execution of output parameter in SSMS

The SP is created in the database and it has returned the expected outcome. Now we need to move to ADF.

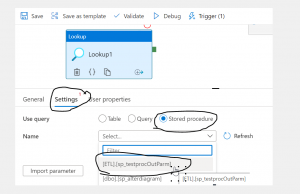
This article assume you know how to add Lookup activity to ADF pipeline. In your pipeline get the Lookup activity as like figure 1.1.Now, Go Settings of the Lookup activity and choose stored procedure from theUse query selections (as shown in Figure 2). Then you should able to see the stored procedure under the dropdown list which you just created in the database. If you are not able to see the stored procedure then it most likely a problem with your access in ADF. Please remember, though you can execute the SP in SSMS, this doesn't mean you will have access to the stored procedure from ADF, You will need to talk with your portal admin and find out if your user has been given enough permissions to execute the stored procedure.

Fig 2: Connect stored procedure via Lookup in ADF

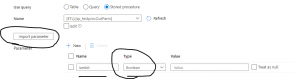
If you find out the stored procedure in the list,  you can continue to the next step. The next step is to import parameters by clicking the button, import parameter, as shown in Fig 3.

Fig 3: import parameter

The import parameter will load all the SP parameters, both input and output parameters. In this case the single output parameter will be shown. Having an output parameter means you want to return some value from the stored procedure and use it in ADF. In this example, the return value will control the next activities in the pipeline. Let's store the return value into a variable.

Drag and drop the Set Variable activity and connect it with the with the Lookup, as shown below in Fig 4

Fig 4: Add Set variable

We need a variable as shown in Fig 5, put variable name and select type of the variable. Since variable is at pipeline scope, so make sure you have selected pipeline itself not any activities in the pipeline.

Fig 5: Creating variable

While creating variables, you will find there are three types of variables: string, Boolean and Array. We have chosen Boolean type for the variable since our stored procedure returns Boolean.

Fig 6: Creating variable

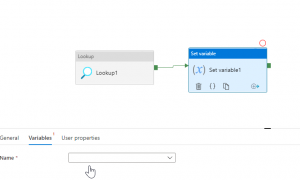
Now, let's get to the pipeline and select 'set variable' activity (as shown in Fig 7). In the Set variable activity, please click the variable tab. Here is where you will find the recently created variable under the name drop down. Select it, as shown in Fig 7.


Fig 7: Choose the variable

To bind the value returned from the stored procedure to the variable, you need write the expression under the 'value' of the variable, as shown in Fig 8

Fig 8: expression to hold return value

The expression to bind return value from stored procedure is:

@activity('Lookup1').output.firstRow.Iambit

Let's explain what expression means. The above expression will return first row from the lookup activity, named Lookup1, and return the column name from the stored procedure, which is 'Iambit'. Here, 'Iambit' will return the result as 1 (a Boolean TRUE).

Be Cautious: Though the variable is set to be Boolean and the stored procedure returned the value as a bit, I found an error in the ADF with the above expression. I had to modify the expression to explicitly convert the return value to Boolean, like the code below:

@bool(activity('Lookup1').output.firstRow.Iambit)

In summary, output parameter in stored procedure a great facility when in need and happy to see that works in ADF. Please note that, the example we depicted here in this article by using very simple stored procedure, however; in business scenario your stored procedure could be a bit complex. For example, you may have logging tables in the data warehouse and you want any activity in ADF will only execute when you pass particular pipeline name as input parameter as a return if the stored procedure returns TRUE.

Saturday, November 14, 2020

How to deal with NULL in ADF dataflow compared with SSIS?

When you are working with ETL/ELT, sometimes you may need to transform NULL into something meaningful value. If you worked with SSIS, you know how you handle that. This blog post will describe how do we do in SSIS and how the very same task can be done in ADF Dataflow.

 Consider, we have a .csv file where Name columns have NULL value for 2nd record (figure: 1.0)


Fig 1.0: Sample .csv file with NULL record


After connecting the .csv file through flat file source in SSIS data flow, we can debug and view the record through data viewer which will look like below figure 1.1

Fig 1.1: Result in SSIS data flow - data viewer


If you would like to replace the NULL value with meaning value, in that case you need to use derive column activity and use expression.

SSIS data flow expression got REPLACENULL function, which will replace NULL to the expected value that you want.

The expression: REPLACENULL(Name,"Unknown")

The above expression will return 'Unknown' when Name is NULL otherwise it will return the original value.

Fig 1.2: Expression in SSIS Data flow to replace NULL with 'Unknown'


When it comes to ADF data flow regular expression similar like SSIS expression; isNull only give you true or false. And isNull function take only one argument, e.g. below fig 2.1 took the argument Name and return True (✓) if the value is NULL.


Fig 2.0: ADF dataflow isNull function


Now, let's find out how to transform NULL value into something meaningful in ADF data flow. ADF doesn’t have the same function REPLACENULL which used in SSIS, rather there are two ways you can replace the NULL values in ADF dataflow.


Approach 1: Combination of iif and isNULL function


Expression: iif(isNull(Name), 'Unknown', Name)

The function iif will check the condition isNull(Name), if Name have Null value it will return 'Unknown' otherwise original value will be returned.


Fig 2.1:  using iif and isNull in ADF dataflow

Approach 2: By using iifNull function

The smartest solution is to use iifNull which will return exactly the same result we found via approach 1.

expression: iifNull(Name, 'Unknown') will return 'Unknown' if Name have NULL values otherwise it will return original value.

Fig 2.2:iifNULL function to replace NULL value

In summary, expression is similar to replace NULL values for both SSIS and ADF data flow, however, the function you need to use is different for two different tools.

Sunday, October 18, 2020

How to handle Case statement in Azure Data Factory (ADF) compare to SSIS?

This post will describe how do you use CASE WHEN statement in Azure data factory(ADF). If you are coming from SSIS background, you know a piece of SQL statement will do the task. However let's see how you do it in SSIS and the very same thing can be achieved in ADF.

Problem statement:

For my simple scenario, In case PortfolioTypeCode is either 'Mutual Fund' or 'Pooled Fund' it should return 1 Else it should return 0.


How do you do in SSIS?

In SSIS, under data flow you will have OLEDB source like below fig 1:

Fig 1: SSIS OLEDB source


And open the OLEDB source and then Write SQL command like below and you are done:

SELECT Col1,

          CASE WHEN PortfolioCode IN('Mutual fund','Pooled fund')

            THEN 1

            ELSE 0

END  IsFund,

Col2

From Table1

Fig 2: CASE WHEN under SQL command in SSIS


How do you implement in ADF?

However in ADF, to achieve the same you need to use Expressions. ADF have very same concept of data flow like SSIS. In the data flow, after the source dataset is established you can add 'Derived Column' activity like below Fig 3:

Fig 3: Adding derive column under data flow


Now you can give a new column name and then add the expression (Fig 4):

Fig 4: Derived column expression


Let's see how Case expression works: it takes 3 arguments, those are condition, true and false. However, it can have alternating condition which describe in the figure 5:

Fig 5: Case in Expression


For my simple scenario, If PortfolioTypeCode is either 'Mutual Fund' or 'Pooled Fund' it should return 1 Else it should return 0.

Since you can't have CASE WHEN rather using case as Expression, the code will look like below:

  case( PortfolioTypeCode=='Mutual Fund',1,

       PortfolioTypeCode=='Pooled Fund',1,0)


Saturday, August 22, 2020

How to solve Azure data factory Error: Sink dataset filepaths cannot contain a file name ?

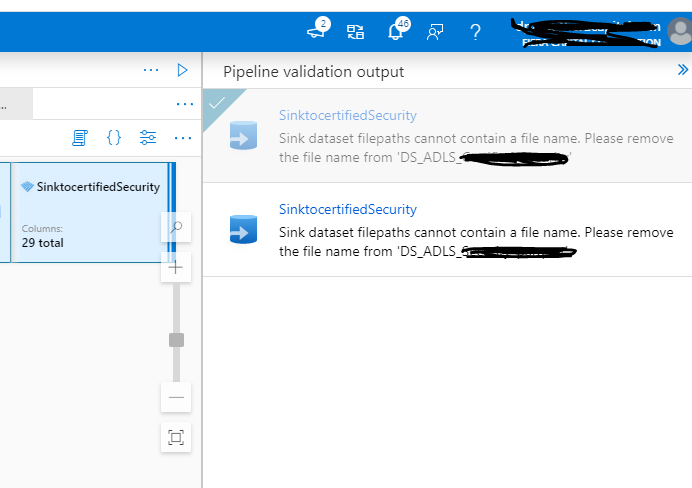
I was building a pipeline which was taking data from SFTP folder and sink to Cleansed layer where file format was .parquet. As soon as validated the pipeline got the below error, where the error message is: 'Sink dataset filepath can not contain a file name, please remove the file name from {DatasetName}.

You will find error like this:

Fig 1: Sink dataset error


If you find this error, may get confuse at first since you have file name at two different places. One is at Sink activity settings and other one is at the data set.

Let's guide you to how to find those settings and fix this error. If you look at the Settings for Sink activity, you will find like below fig: 2.


Fig 2: Settings of Sink activity


The error message said filepath can't contain file name but remember this is not data set, it's setting of the Sink activity so you don't need to remove the file name. And if you want to keep it in a single file then choose 'Output to single file'.

So fix the issue you need click Sink and open data set as like below fig 3:

Fig 3: open data set


Now you can find the file name under data set as like below fig 4, Please remove file name, save and validate.

Fig 4: remove file name from Data set

Now the error will disappear. Lesson learned, look at the error message more than once and locate the correct place to fix the issue.


Wednesday, February 19, 2020

What is Linked services in Azure Data factory(ADF)?

If you are new to Azure Data Factory and started to build the very first pipeline. Assuming, you already found the source and target. Your source data either from on premise or cloud database or blob storage or from any Web API. Whether you connect with storage account or on-premise /cloud database you require Linked Services. Linked Services is like Connection string.

For example, if you like to get data from Blob storage and insert into the cloud database then you will require two linked services. One linked service is your source connection from blog storage to the data factory and another is the target connection which connect from data factory to database.


Creating Linked service is easy, following a few steps via wizard, however; when you create Linked service  one of the step will be creating or using called Integration Runtime.  Since there are three different type of Integration Runtime (IR), you may get confuse with which one to choose:

Let's explain three different type of Integration Runtime,

1. Azure
2. Self-Hosted
3. Linked Self-Hosted

Please note that, there is one more Integration Runtime which called Azure-SSIS integration Runtime, this IR is required when you shift your SSIS package to Azure. We will not cover SSIS IR in this post.

1. Azure
It's the default IR, means if you don't create anything then it will create automatically and give the name as 'AutoResolveIntegrationRuntime' like as below figure 1.

Fig 1: AutoResolveIntegrationRuntime

If the data integration capabilities like Data Flow, Data movement and Activity dispatch is under public network then 'Azure IR' is used. If Azure IR is not automatically created then you can create manually by clicking the '+New' like below fig 2


Fig 2: Choose to create IR

 and you will find below window to create Azure IR (Fig 3)

Fig 3: Choose from different IR

When IR is created, you can find them running under data factory-> Connections

Fig 4: IR running under Data Factory


2. Self-Hosted:

If the source or target is under private network e.g. database maybe resides on premise in that case you must need to create Self-Hosted Runtime. There are a few steps to create Self-Hosted Runtime. While you are working with Azure Data factory, you can create it via data factory UI.
please follow the link to create Self-Hosted IR : https://docs.microsoft.com/en-us/azure/data-factory/create-self-hosted-integration-runtime#create-a-self-hosted-ir-via-azure-data-factory-ui


3. Linked Self-Hosted: 

If you already have Self-Hosted IR and need to use the same for other Data Factory then you don't need to create  new Self-Hosted IR rather you can link the existing Self-Hosted to the other data factory.


Saturday, January 18, 2020

Azure Data Factory: How to add and remove code repository to ADF

If you are working with Azure data Factory (ADF), the very first step of the development is to connect with code repository, well!!  you can develop without connecting code repository but  collaboration work and version control can't be there.

In general when you work with ADF and publish code is saved under ADF service but no repository is there means you can't see who saved the code or which version of the code you are working with.
For example, below Fig 01 give me option to choose from ADF mode or use Github. If I choose ADF mode then there will be no repository for the project, however; with Github I will have that option.


Fig 01: ADF repo ot ADF mode

Step 1: Create source source repository

If you have visual studio subscription then you can get free azure DevOps account and then create repository there, if don't then please go to  Github (https://github.com/) and create a repository which is completely free. It's very simple to create a repository in Github, just a few click.


Step 2: Login to Azure Data Factory and choose relevant repository type

Let's log into the Azure Data Factory and after clicking 'Author and Monitor' you will have the page for the development work. At the top left of the page like below Fig 02, you will find option called 'Set up Code repository'.

Fig 02: Set up Code repository

And you get options to choose from either Azure DevOps Git or Github (see above fig: 02). If you already have visual studio account then you can choose 'Azure DevOps', otherwise you need to use Github.

For example, in my case; I logged in Azure portal with my personal account and the account doesn't have any association with Visual studio account. So when choose 'Azure DevOps' nothing is showing(Fig 03)
Fig 03: Azure Devops require VS account


Step 2: Settings for the chosen repository type

Let's go to the next step where you have already chosen repository type 'Github' and now please fill up the necessary information as like shown in figure 04.


Fig 04: Detail for GitHub

Github repository is added to the Azure data factory, so it's become easy to collaborate and deploy the pipeline.

Fig 05: Repository is connected


Removing Code Repository:

The code repository have been added for ADF, however, for any reason if you want to remove the repository, then?


You need to find out 'repo settings', Please come out from Author tab and switch to Home tab to find 'repo settings' as like figure 06.

Fig 06: Find Git repo


As long as you click the 'repo settings', you will find below screen (Fig 07)  there will be option to remove the repository, just click the 'remove git' you are done!!

Fig 07: Removing Git repo